Henrik Schmid · 13 October 2026
Leveraging Cross-Platform Integration Methods to Refine Enterprise Data Accuracy Metrics
Enterprise systems often span multiple platforms that each generate their own datasets, and organizations continue to refine how those platforms exchange information to improve overall data accuracy. Cross-platform integration methods bring together structured records from cloud services, on-premises databases, and third-party applications through standardized APIs and middleware layers. Research from government statistical agencies shows that unified data pipelines reduce duplication errors by aligning timestamps, identifiers, and validation rules across sources.
Core Integration Approaches in Use Today
Many enterprises rely on real-time synchronization protocols that push updates between customer relationship management tools and enterprise resource planning systems while maintaining audit trails for every change. Batch processing remains common for high-volume historical records, yet observers note that hybrid models combining both methods deliver more consistent results when accuracy metrics are tracked at regular intervals. Data mapping tools convert formats automatically, and validation scripts check for inconsistencies before records enter the central repository.
Standard Protocols and Their Role
Protocols such as RESTful APIs and message queues allow different software environments to exchange information without custom code for every connection. According to reports from the Australian Bureau of Statistics on data quality frameworks, organizations that adopt open standards see fewer mismatches in numerical fields and categorical labels across departments. These standards also support encryption during transfer, which helps preserve integrity when data moves between secure zones.
Metadata repositories store definitions for each field so that teams can verify meanings before integration occurs. When field names differ across platforms, automated reconciliation engines compare values against reference tables and flag discrepancies for review. Studies from academic research centers indicate that such repositories cut the time spent on manual corrections by providing clear lineage for every data point.
Measuring Accuracy Improvements
Accuracy metrics typically include completeness percentages, error rates per thousand records, and consistency scores across linked tables. Before integration projects begin, baseline measurements establish current performance levels, and post-implementation tracking reveals whether error rates decline as expected. Figures from Canadian government data initiatives reveal that integrated environments often achieve 15 to 20 percent reductions in missing value incidents within the first year of deployment.
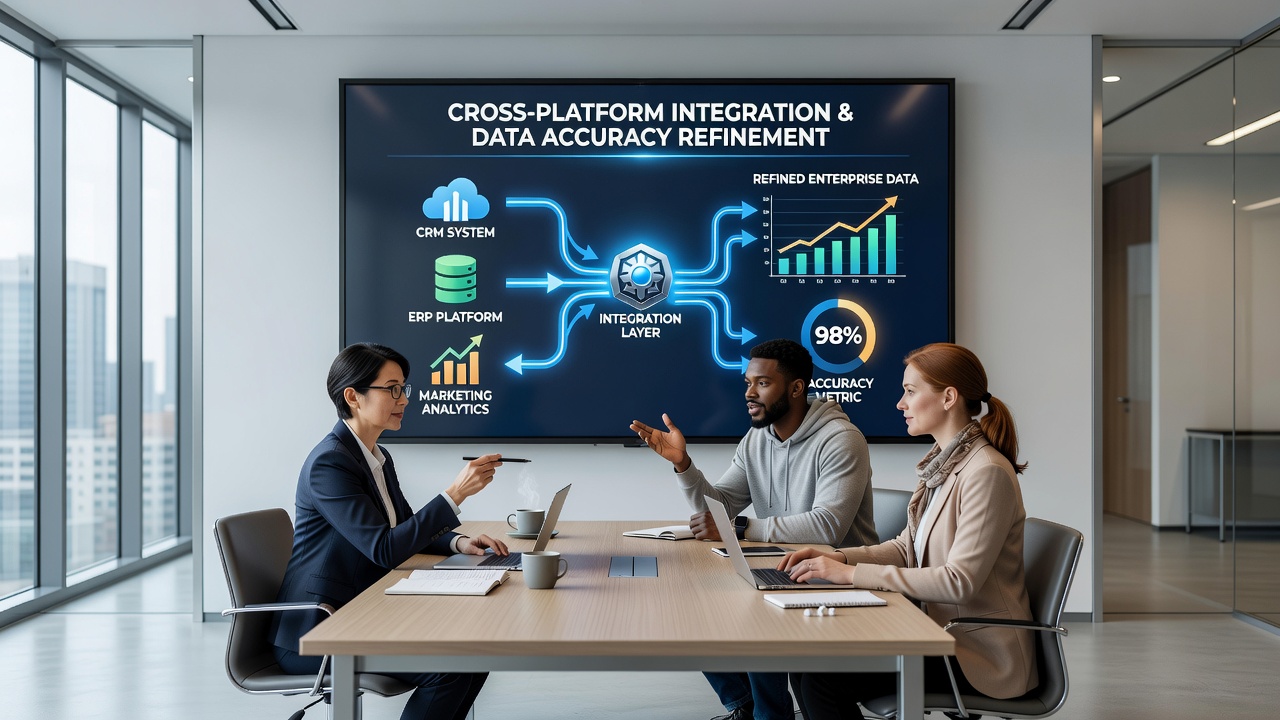
One study conducted by university researchers tracked a multinational firm that connected its supply chain platform with financial reporting tools. The project introduced automated reconciliation checks that compared order quantities against invoice totals in near real time. Results showed a measurable drop in variance reports, and the company documented fewer instances where inventory counts failed to match ledger entries.
Implementation Patterns Observed Across Sectors
Financial services firms frequently combine trading platforms with compliance databases to ensure regulatory reports reflect the same transaction details stored in operational systems. Healthcare providers link electronic health record systems with billing platforms so that patient identifiers remain consistent when claims are generated. Manufacturing operations connect factory sensors to inventory management software, allowing production counts to update stock levels without manual entry steps.
Each sector adapts the same core methods to its specific data types. In October 2026, preparations for updated international data exchange guidelines are expected to influence how enterprises configure their integration layers, particularly around timestamp synchronization and identifier uniqueness requirements. Organizations already using extensible schemas find it easier to incorporate those forthcoming adjustments.
Challenges and Technical Considerations
Legacy systems sometimes lack modern API support, which forces teams to build custom connectors that require ongoing maintenance. Data volume spikes during peak periods can strain integration queues, leading to temporary lags that affect real-time accuracy calculations. Security policies that restrict direct database access add another layer of complexity when platforms sit in separate network segments.
Yet enterprises address these issues through incremental rollouts that test small data subsets first. Monitoring dashboards track latency and error counts continuously, and automated alerts notify administrators when thresholds are exceeded. Documentation from the U.S. National Institute of Standards and Technology outlines recommended practices for maintaining data provenance throughout such phased implementations.
Conclusion
Cross-platform integration methods provide structured pathways for aligning records that originate in separate environments, and accuracy metrics improve when validation steps occur at each transfer point. Organizations that maintain clear metadata standards and monitor performance indicators can track progress objectively over successive reporting cycles. As new guidelines take effect in late 2026, the same integration frameworks will support continued refinements in how enterprise data is validated and consolidated.